
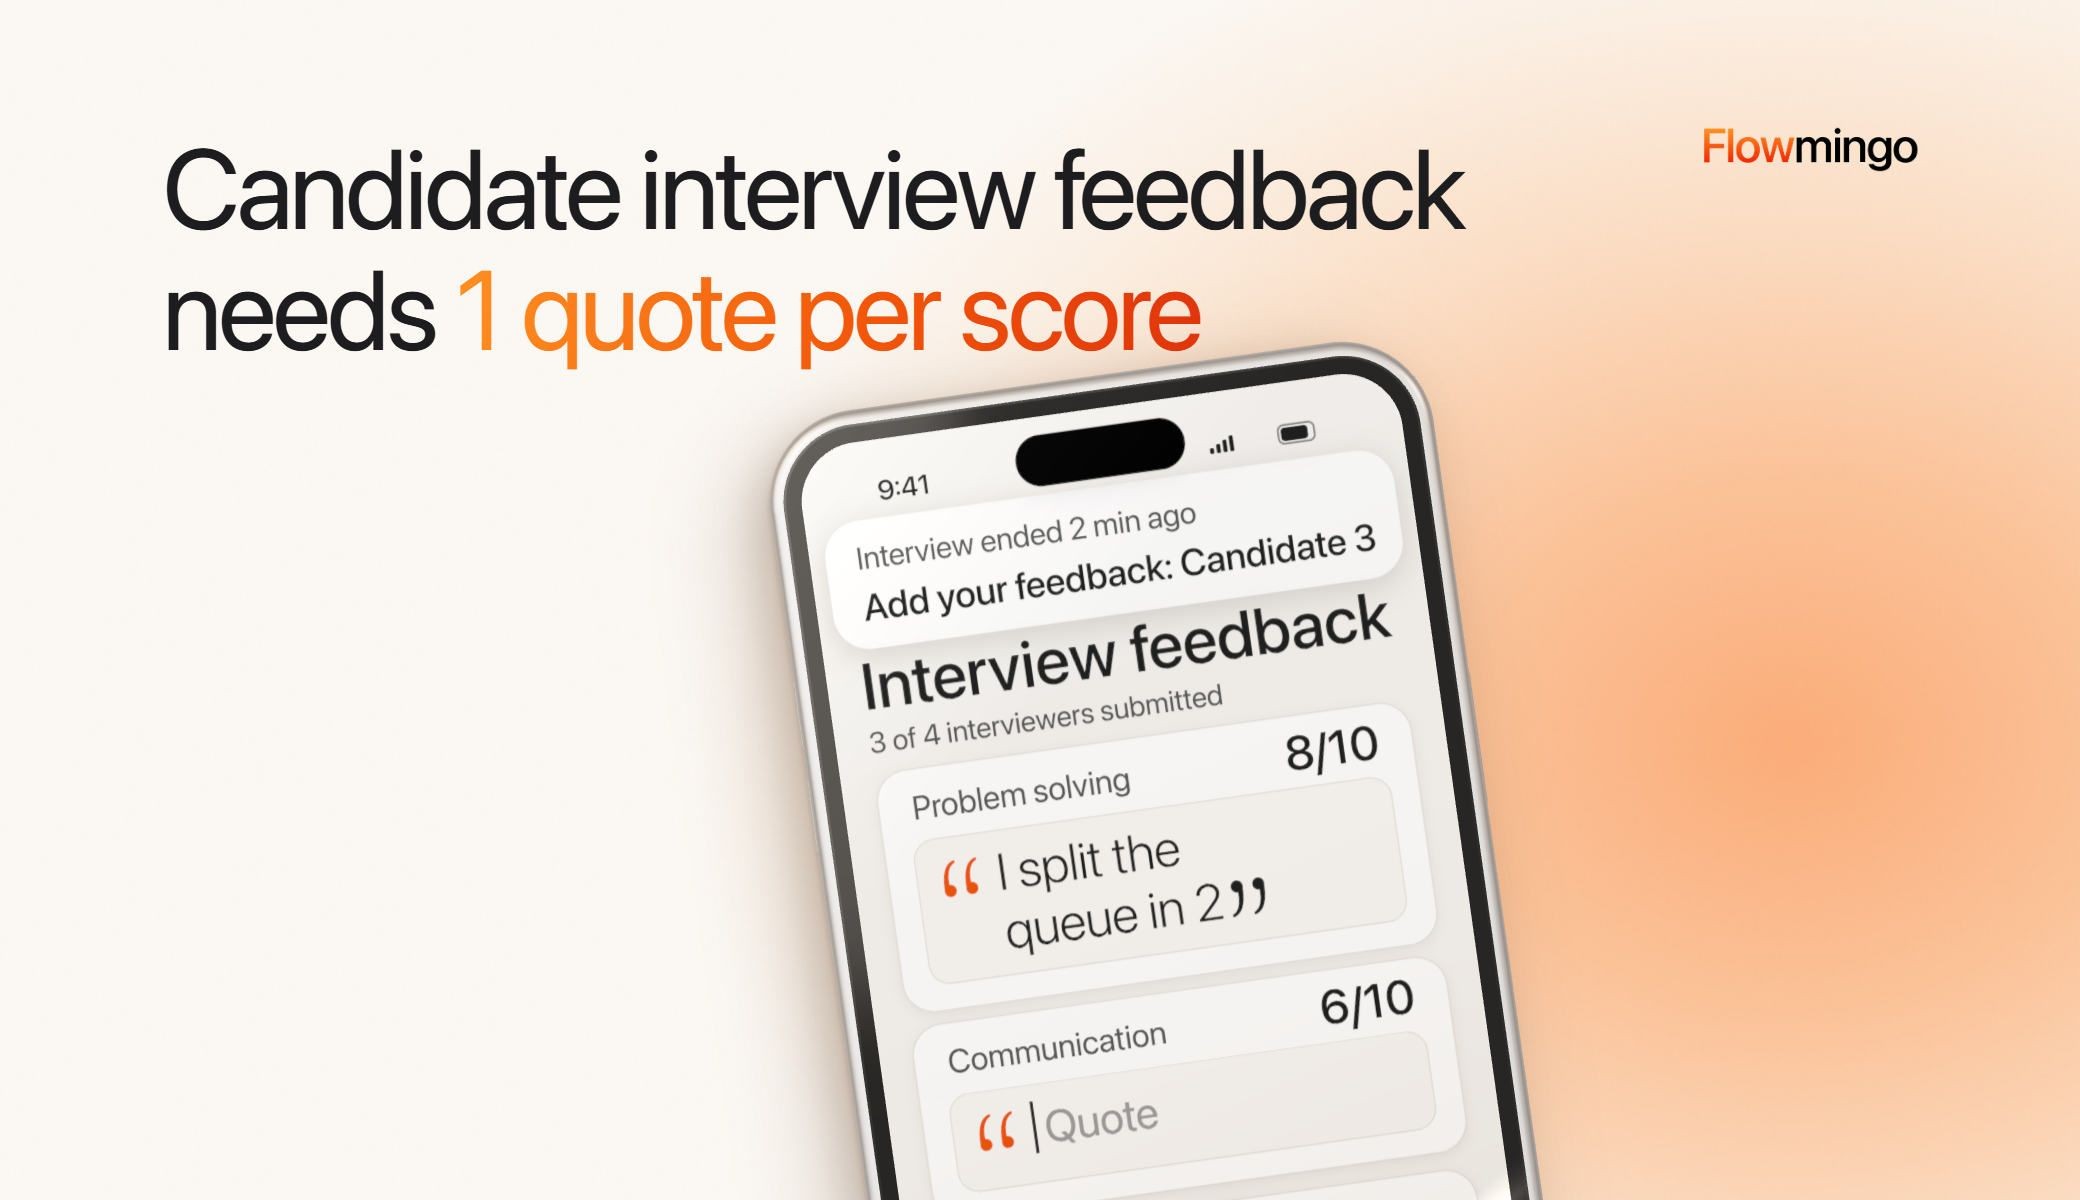
It is Friday, and your candidate interview feedback tool holds 1 scorecard from the 4 people who met your finalist. It says "good culture fit".
You don't need another form. You need evidence.
Your interviewers are not lazy. Most interviewer feedback tools ask for an opinion at the end of a busy day, and the debrief rewards whoever speaks first.
Vague notes cost more than time. In a foundational study of grade predictions, those made after a free-form interview matched actual grades only half as closely as those made without one. Late scorecards also keep the finalist waiting, and 61% of job seekers (Greenhouse, 2024) say an employer ghosted them after an interview.
The fix takes 3 moves. First, each interviewer scores every criterion with 1 quote straight after the interview, and submits within 24 hours. Second, every score goes in before the debrief.
Third, a fixed rule combines the scores, and you discuss only the splits.
Key takeaways
- Which candidate interview feedback tool should I start with? The one that fixes your failure. Each of the 5 kinds fixes a different 1, and a loud debrief needs a process.
- What makes interview feedback usable? A score on each of 4 to 6 agreed criteria, 1 quote per score, and the recommendation last.
- Does structured interview scoring predict job performance? Yes. A large re-analysis ranked them 1st, ahead of ability tests.
- Should the panel decide together in the debrief? Not first. A fixed rule predicted performance more than 50% better than an overall judgement.
- Can AI write or score interview feedback? AI can tidy wording, not add evidence. Trust an AI interview report only if it passes the 5 checks in section 7.
1. Which candidate interview feedback tool fixes late, vague feedback from my interviewers?
Match the tool to the failure: a prompt right after the interview fixes late feedback, and per-criterion ratings with a quote fix vague feedback. Collect every score before the debrief, so the loudest voice cannot win.
Late feedback is a memory problem, because the longer the wait, the less anyone recalls. 1 TA lead posted on Reddit that feedback for a senior engineering role took 3 days, in 1-line replies.
Then an automation asked for structured feedback right after each interview, and 4 of 4 interviewers submitted within 2 minutes. It is 1 team's report, but it shows why a feedback tool should prompt at once.
The candidate feels the delay too. In Greenhouse's 2024 State of Job Hunting report (2,500 workers), 61% of job seekers said an employer ghosted them after an interview.
This guide fixes 4 failures in feedback about a candidate:
- Late: the scorecard arrives days later (this section and section 10).
- Vague: "good culture fit" with nothing behind it (section 2).
- Forgotten: nobody recalls what the candidate said (section 5).
- Loud: the debrief follows the most senior voice (section 9).
Flowmingo data · 49,459 completed AI interviews with a report timestamp · 925 companies · 1 Jul to 15 Oct 2026
- 16 seconds was the median time from the end of an AI interview to its scored report.
- 27 seconds or less was the wait for 90% of AI interview reports in this period.
- 98.5% of these AI interview reports were ready within 5 minutes of the candidate finishing.
This is when Flowmingo's evaluation service stamped its AI report, not when a recruiter read it. It is not a human interviewer's write-up.
In the chart below, 25% of reports were ready within 14 seconds, half of reports (the median) within 16 and 75% within 21.
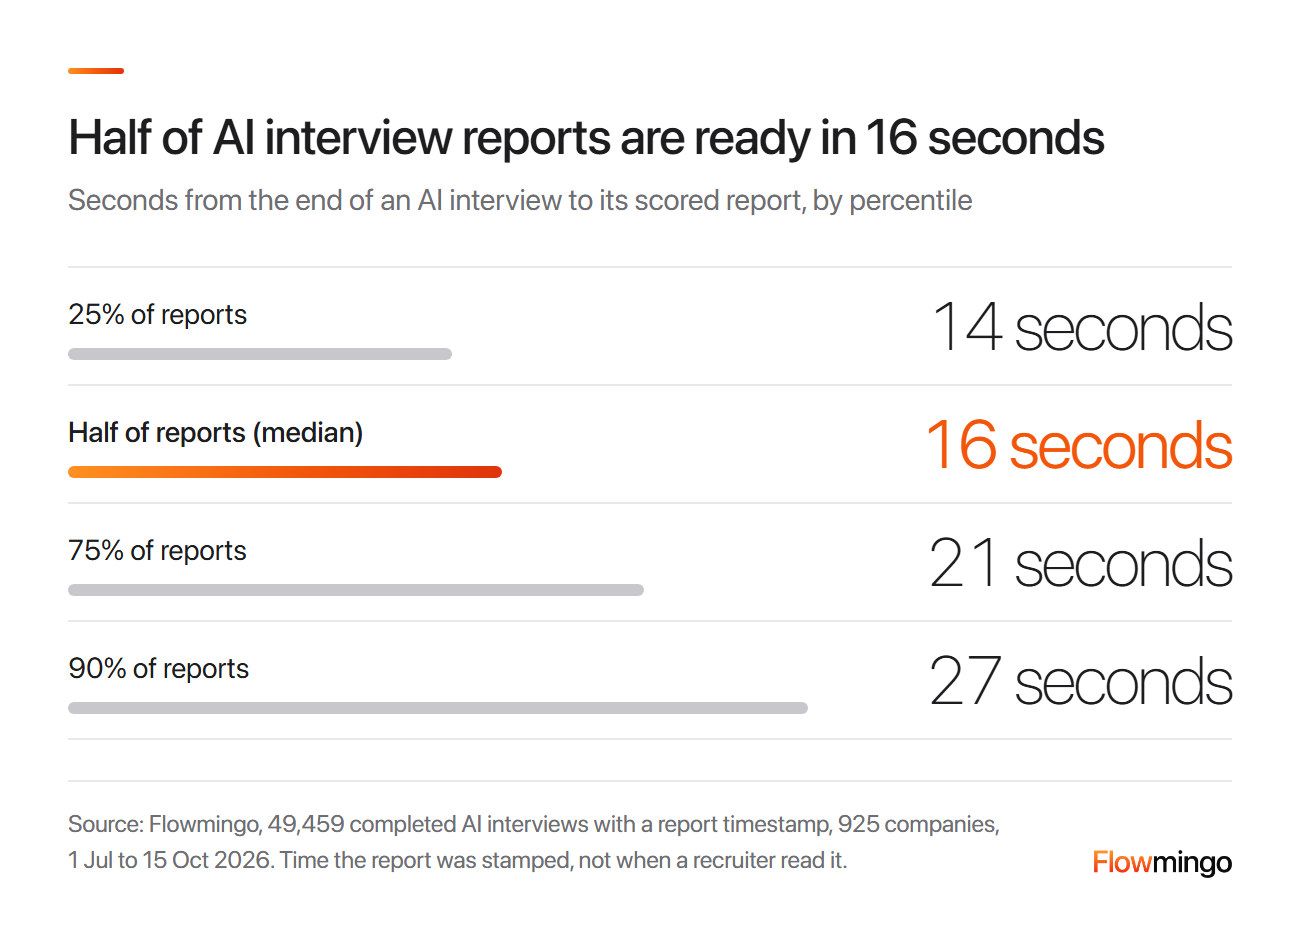
Report speed chart: the median AI interview report was ready 16 seconds after the candidate finished (49,459 timestamped interviews, 1 Jul to 15 Oct 2026).
2. My interviewers write 'good culture fit' and stop. How do I get feedback I can compare?
Ask every interviewer for a score on the same 4 to 6 criteria, with 1 candidate quote behind each. "Good culture fit" with no quote is a feeling, and free-form impressions can make a decision worse.
In Dana, Dawes and Peterson's foundational 2013 study, people predicted students' grades, some after an unstructured interview. Those predictions matched actual grades at .31, against .61 without one, on a scale where 0 is no link and 1 a perfect one.
Prior grades alone scored .65, so the chat added noise. The study predicted grades, not jobs, yet 96 of 169 people (57%) still ranked an interview with random answers above none.
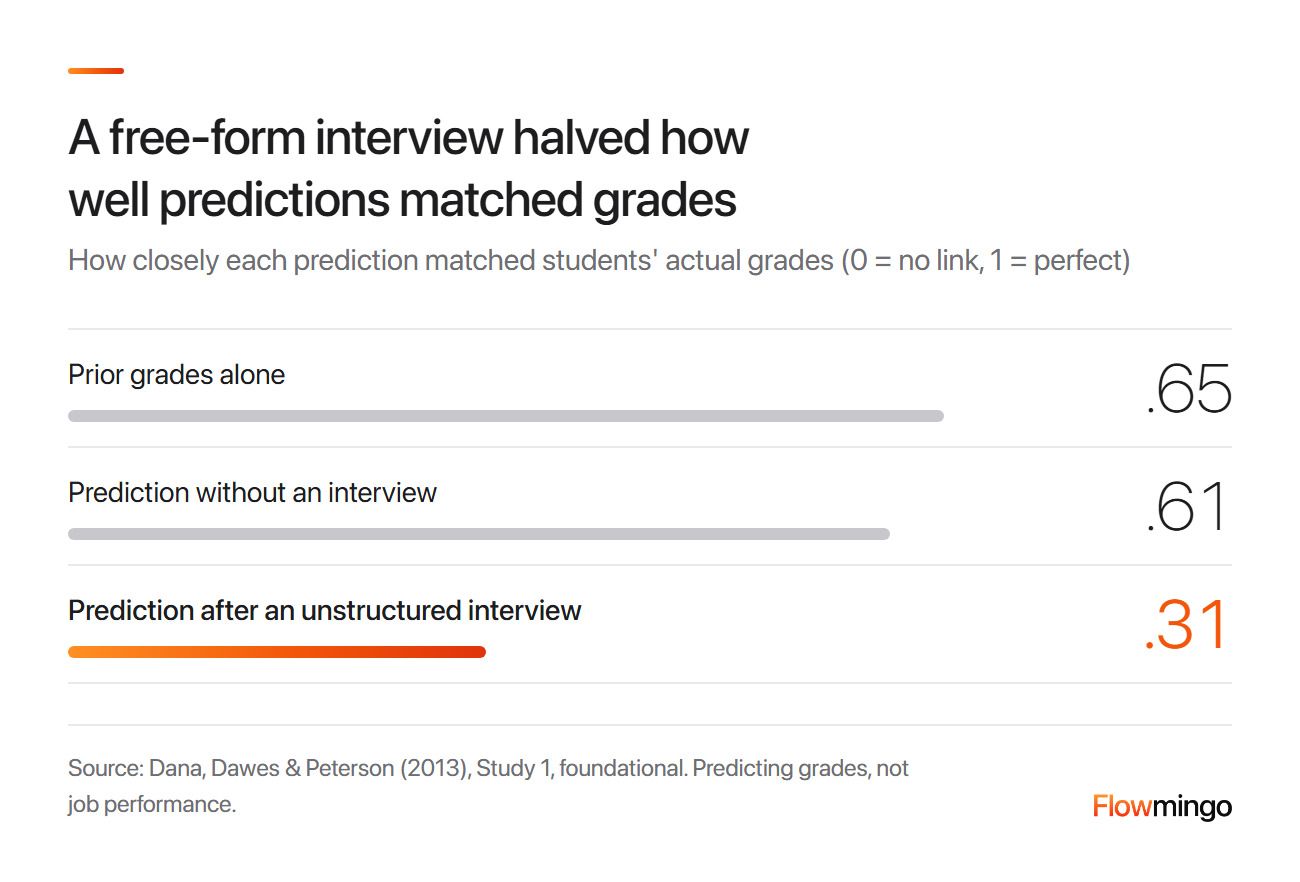
Unstructured interview chart: predictions after a free-form interview matched grades at .31, against .61 without one and .65 for prior grades (foundational).
The fix is a quote rule. 1 hiring committee that kept getting "I liked them" began requiring 1 direct candidate quote per write-up, and the quality changed (r/recruiting).
Replace "culture fit" with the behaviour the job needs. For example, "explains a decision to a customer in plain words" is a criterion 2 people can score.
A record tied to job criteria is also your evidence if a rejection is challenged. Singapore passed its Workplace Fairness Act on 8 January 2025 (MOM). It is expected to take effect by the end of 2027 and will cover 11 characteristics, such as age and race (Hawksford).
Here is 1 Customer Support Team Lead, written up twice. Before: "Great candidate. Strong communicator. Good culture fit. Hire." After (illustrative, not customer data):
| Criterion (importance) | Score 0-10 | Evidence in the candidate's words | Concern or what to probe |
|---|---|---|---|
| Role and stage | -- | Customer Support Team Lead, 2nd interview (panel) | -- |
| Handling escalations (Must Have) | 8 | "I took the 3 angriest tickets each morning and wrote our reply macro" | How they teach it |
| Coaching a team (Very Important) | 5 | Described a weekly 1:1, no example of improving anyone | Name 1 agent they improved, and how |
| Using support metrics (Important) | 7 | "First-reply time went from about a day to 4 hours after we split the queue" | Check what "about a day" means |
| Writing for customers (Good To Have) | 6 | "I keep every escalation summary to 3 lines" | Ask for 1 real summary |
| Recommendation (written last) | -- | Proceed to the final round | Probe coaching first |
| Submitted before reading others | -- | Yes, 2 hours after the interview | -- |
Our interview scorecard template anchors a 1-to-5 scale. Any scale works if every interviewer uses the same one.
2.1 How to provide feedback on an interview candidate?
Score each criterion right after the interview, before memory fades and before you read anyone else's notes, and submit within 24 hours at the latest. Use these 6 fields:
- Role and interview stage.
- A score on each agreed criterion, on your scorecard's scale.
- 1 quote or observed action behind each score.
- Concerns, written as what the next interviewer should probe.
- The overall recommendation, written after the scores.
- Submitted before reading anyone else's feedback: yes or no.
3. Does structured interview scoring actually predict who will do well in the job?
Yes. In a foundational 2022 re-analysis, structured interviews were the top-ranked predictor of job performance, at .42 against .31 for cognitive ability tests.
They are correlations from Sackett, Zhang, Berry and Lievens, where 0 means no link to later job performance and 1 a perfect link.
So .42 is not a 42% hit rate. It is the strongest link of the methods reviewed, as SIOP's summary explains.
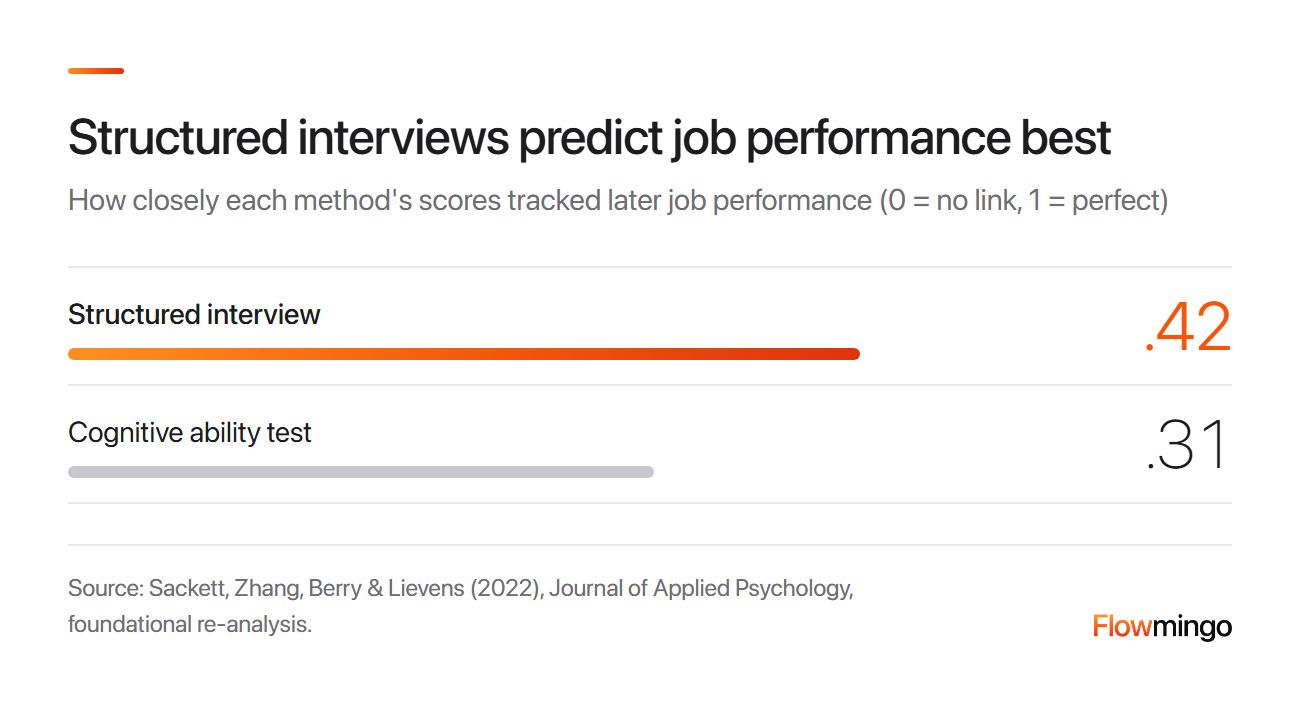
Predictor chart: the structured interview ranked first at .42, ahead of the cognitive ability test at .31 (foundational 2022 re-analysis, Sackett and colleagues).
A fair objection on Hacker News is that scorecards put numbers on opinions. The point is 1 yardstick for every candidate, with each criterion scored on its own.
In Kuncel and colleagues' foundational 2013 meta-analysis, combining ratings with a fixed rule predicted job performance more than 50% better than holistic judgement.
Holistic means forming an overall view from everything, even by experts. The rule wins because it weighs the same evidence the same way for everyone.
Here is a weighted average agreed before the interviews, with illustrative numbers: 4 criteria weighted 4, 3, 2 and 1, as in section 7.
Finalist A scores 5 on the Must Have and 8, 7 and 7 on the rest, so 6.5. Finalist B scores 8, then 6, 7 and 6, so 7.0.
The panel's gut picked A, who won 2 of the other 3 criteria. The rule picks B, so you discuss only the Must Have, where they split by 3 points.
Our structured interview guide covers the questions. In any candidate interview feedback tool, no score per criterion means no structured interview.
4. Note-taker, scorecard, AI writer, AI interviewer or survey: which candidate interview feedback tool do I need?
Each of the 5 kinds fixes a different failure from section 1. Scorecards fix vague feedback, note-takers fix forgotten details, and AI interviewer reports fix late and vague feedback at round 1.
Text generators fix only wording, and surveys solve a different problem. A loud debrief needs a process (section 9), not a tool.
1 recruiter comparing BrightHire, Metaview and Otter found vendor sites "all vague about AI" (r/recruiting).
| Kind of tool | Failure it fixes | Leaves broken | Examples |
|---|---|---|---|
| ATS scorecard | Vague, with 1 format in 1 place | Late or empty forms, no evidence | Greenhouse, Ashby (in Metaview's list), Polly's Slack form |
| AI note-taker | Forgotten details | Judgement and scoring | Metaview, BrightHire |
| Feedback-text generator | None of the 4: messy wording only | Missing evidence | TalentEconomy, Easy-Peasy |
| AI interviewer with a scored report | Late and vague, with evidence at round 1 | The human final round | HireVue (top 10) |
| Candidate survey | None: candidate experience is a different problem (section 8) | Interviewer judgement | Survale, Typeform |
ATS scorecards put feedback in 1 place, but nothing chases the people who skip them. A Greenhouse user went looking for a report of candidates whose scorecards were never submitted (r/recruiting). So check that a tool shows who has not submitted.
AI note-takers record the call and draft notes, and Metaview's comparison page ranks Metaview first of 7. If interviewers score but cite nothing, a transcript gives them the quote.
Feedback-text generators turn pasted notes into tidy text. TalentEconomy's generator promises results "in seconds" and cites no research, so feed one notes with no quote and check it adds nothing.
AI interviewers, such as HireVue's AI interviewer, run a structured first interview and return a score per criterion with reasons and a transcript. Nobody writes round 1 up, so check you can see the words behind every score.
Candidate surveys measure how candidates felt about your process (section 8), not how well anyone judged. Before you buy interview feedback software, name the failure you see most, because that names the row.
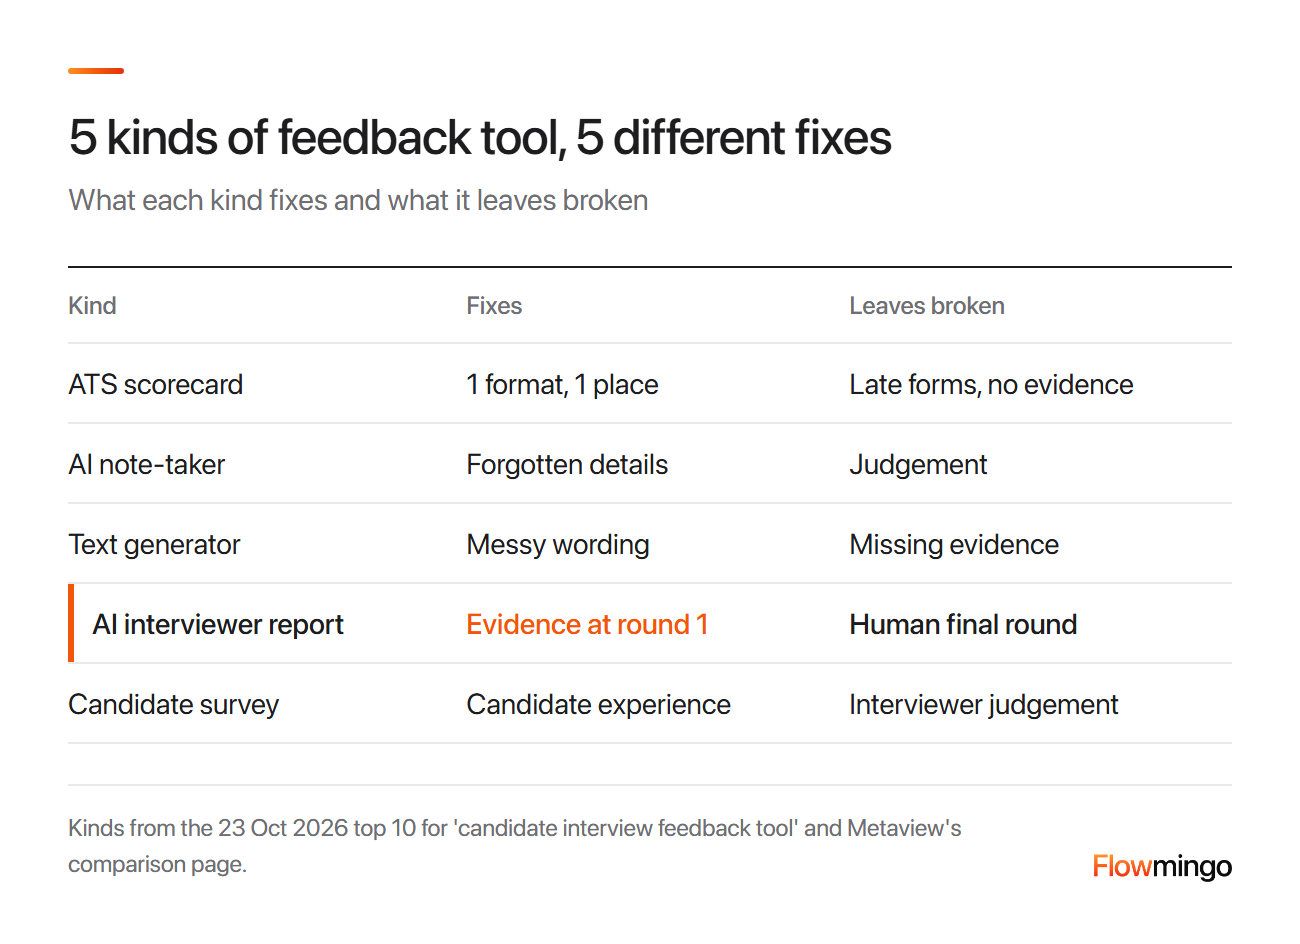
Tool map: ATS scorecard fixes 1 format, 1 place, AI note-taker fixes forgotten details, and text generator fixes messy wording. AI interviewer report fixes evidence at round 1, and candidate survey fixes candidate experience.
5. Is an AI note-taker like Metaview worth it, or will my ATS scorecard do?
A note-taker fixes forgetting, not judging. Add one if interviewers already score in the ATS but lose details, because a transcript won't make anyone fill in a skipped scorecard.
In a foundational 2002 experiment, Middendorf and Macan found that taking notes improved how accurately interviewers recalled an interview, not how accurately they judged it. Reviewing their notes did help judgement, but only for people who had taken conventional notes.
That study used handwritten notes, so applying it to AI transcripts is our inference. Recall helps only if someone then scores against criteria.
So the ATS scorecard owns the criteria and the scale, and a note-taker should write into it. 1 recruiter wrote: "Metaview doesn't integrate with our ATS but Quil does" (r/recruiting).
Metaview's comparison table, read on 23 Oct 2026, lists Metaview as free with a work email and HireLogic from $69 per user a month. Check what a free tier stores, and for how long.
Recording also means consent and a retention rule. The UK ICO's audit of AI recruitment tools, announced in November 2024, found some kept candidate data indefinitely and made almost 300 recommendations.
To test it, have each interviewer score 3 interviews from memory, then again with the transcript. If quotes appear, the note-taker earns its place.
How Flowmingo helps
Flowmingo scores its own AI interview. It does not record, transcribe or score your live or panel interviews, so a note-taker and Flowmingo do different jobs.
6. Can AI write my interviewers' feedback for them, and is that a good idea?
AI can tidy the wording, but it can't add evidence the interviewer never wrote down. Use a generator only after the scores and quotes exist, never in place of them.
TalentEconomy's own FAQ says it does not add information you did not provide. Easy-Peasy's generator takes 2 inputs, a job title and your notes.
Polly's feedback template is a form, not a generator: it gathers panel feedback in 1 place. It asks for 1 overall rating with no anchors and ends on "Hire or no hire?". Drop its "would enjoy working alongside this candidate every day" item.
The risk is that polished text from vague notes reads like evidence, though it changes nothing the interviewer saw.
AI writing helps in 2 places. It can turn a finished scorecard into a summary for a manager who missed the interview, and draft questions from the "what to probe" line.
For example, "no example of coaching" can become 2 final-round questions: which agent they improved, and how their numbers changed.
Pasting candidate notes into a public chat tool also sends personal data to a third party.
7. Can I trust an AI interviewer's scored report, and see why it scored someone that way?
Trust it as far as you can check it. Every score should name the criterion, give a written reason and lead you to the candidate's own words, and a person should make the call.
Early independent evidence comes from a 2026 working paper by Rubin and Grissom, not yet peer-reviewed. In it, 6 language models scored aspiring school principals' hiring-assessment answers, including a structured interview question.
It is education hiring, and none of the models were Flowmingo's.
3 of the 6 often agreed with the human average more closely than trained scorers agreed with each other. So rubric scoring by AI can be consistent, more so on concrete criteria than subjective ones, which means your lever is the criteria.
Job seekers are wary of who decides. In a foundational Pew survey of 11,004 US adults from December 2022, 71% opposed AI making the final hiring decision.
Yet 47% thought AI would treat applicants more equally, and 15% said worse. So keep a person deciding, and tell candidates how you use AI. Run these 5 checks on any AI interviewer's report:
- A score per criterion, not just an overall number.
- A written reason for each score.
- Quotes that are exact phrases from the transcript.
- Weights you can see, so you can recompute the overall.
- A person can override, and nobody is rejected automatically.
How Flowmingo helps
Flowmingo's AI interview asks every applicant the same questions, drafted from your job description. It scores each of your criteria 0 to 10, with written reasons, strengths, gaps and a recommendation.
The recording and transcript sit behind every score, so your team can check and override it. How we score shows the weights, from Must Have x4 to Good To Have x1.
A highlight must be an exact transcript phrase. Must Have does not auto-reject, and AI interviews suit high-volume, entry to mid-level roles, not a senior hire's final round.
Flowmingo's public sample report, below, shows each criterion's score and reason. The exact quotes sit in the transcript view, not shown.
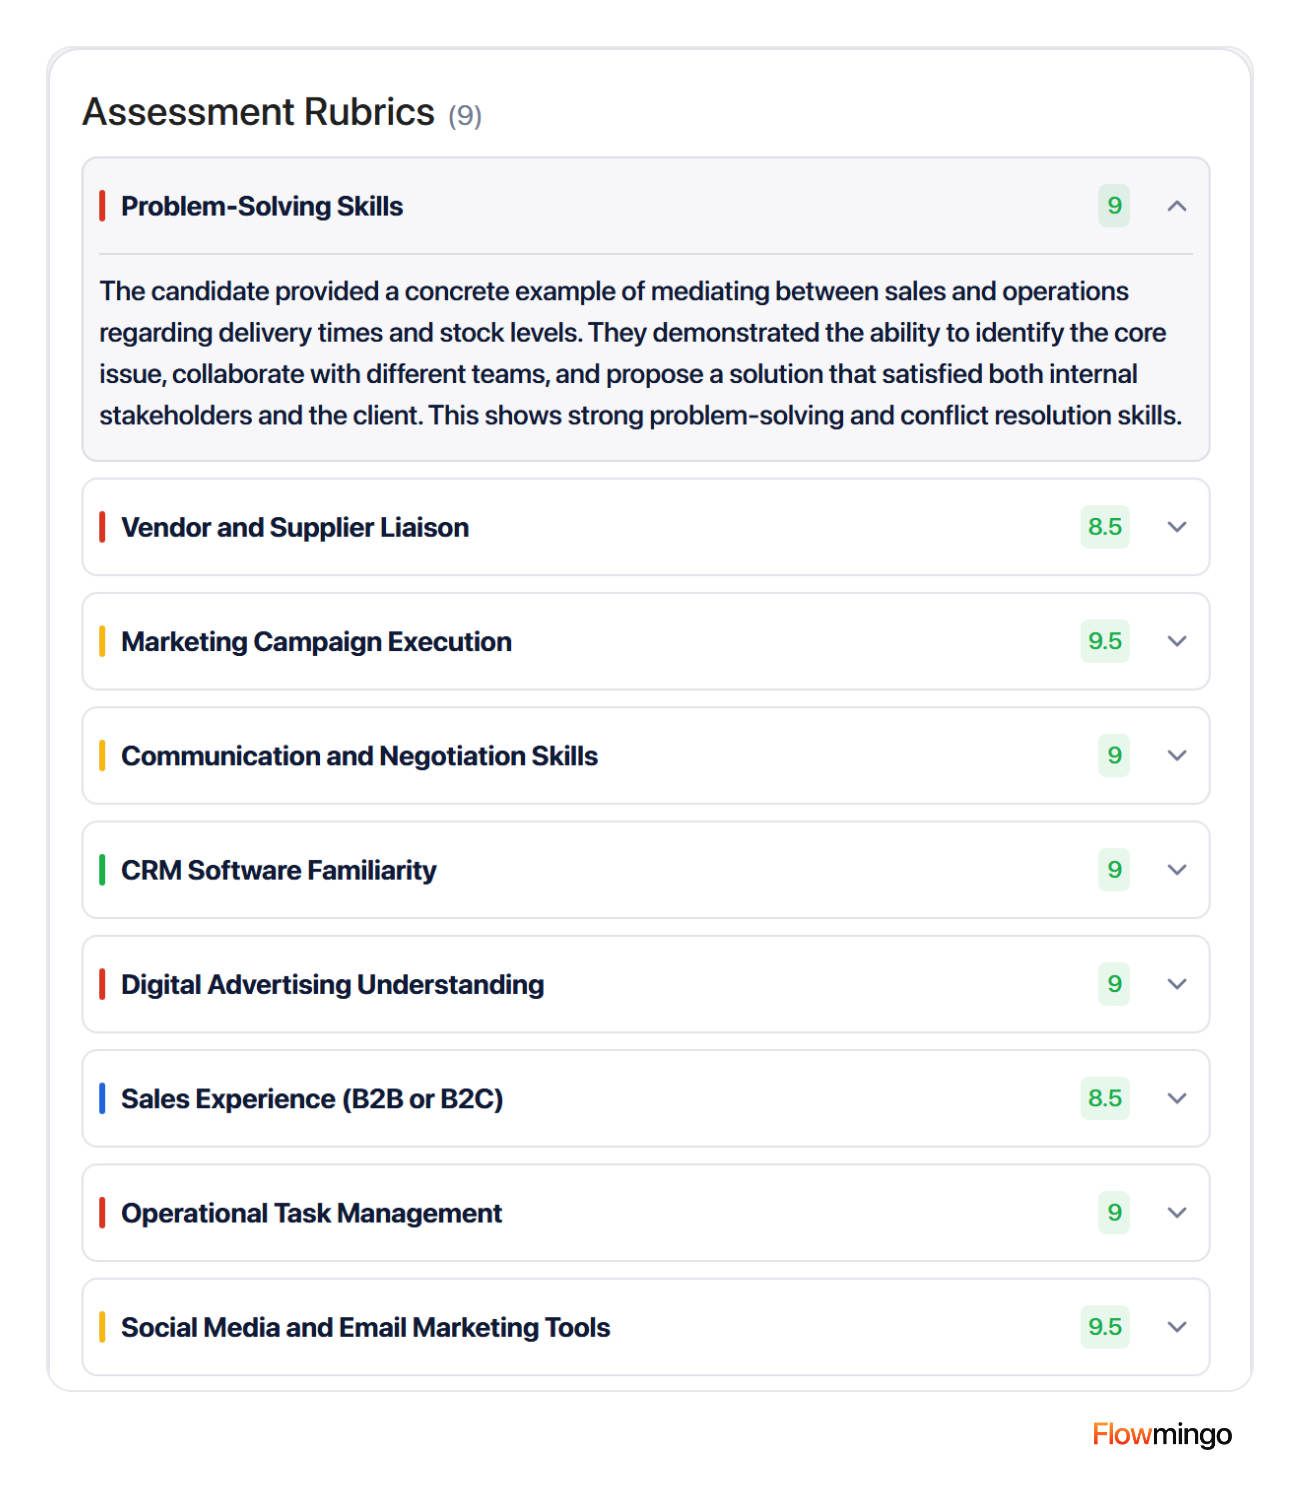
Sample report: each criterion gets a 0 to 10 score and a written reason drawn from the candidate's answers (public demo report, not customer data). The exact quotes sit in the transcript view, not shown here.
Flowmingo data · 49,475 completed AI interviews · 925 companies · 1 Jul to 15 Oct 2026
- 99.96% of these AI interviews came back with an overall score plus written strengths, gaps and recommendations.
- 9 criteria was the median number each AI interview report rated, with the middle half between 8 and 10.
- 99.95% of 515,787 criterion ratings carried a written reason of at least 40 characters.
AI reports on AI interviews, not human feedback or decisions. Criteria figures cover the 49,463 interviews (924 companies) with criterion results. A reason's presence does not measure its quality. Criteria are drafted by AI from the job description and recruiters can edit them, so 9 is what reports contain, not what recruiters chose. Ratings are AI scores, not job performance, and these figures do not show whether a recruiter read the report.
8. Do I need a candidate experience survey, or does that solve a different problem?
A candidate survey solves a different problem. It tells you how candidates felt about your process, not whether your interviewers judged well, so buy one when candidates go silent or drop out.
In Talent Board's foundational December 2024 report, 24% of North American candidates were still waiting 2+ months after applying (Talent Board and ERE).
An earlier 2023 benchmark of 240,000 candidates found 36% of US candidates unanswered 1 to 2 months after applying (SHRM, April 2024). It covers 1 country and a shorter wait.
Survale triggers short surveys at application, interview, offer and hire. Typeform's candidate feedback page names 2 weak spots: low response rates, and answers biased by whether the candidate got an offer.
Neither tells you whether an interviewer scored fairly, because the candidate never sees the scorecard.
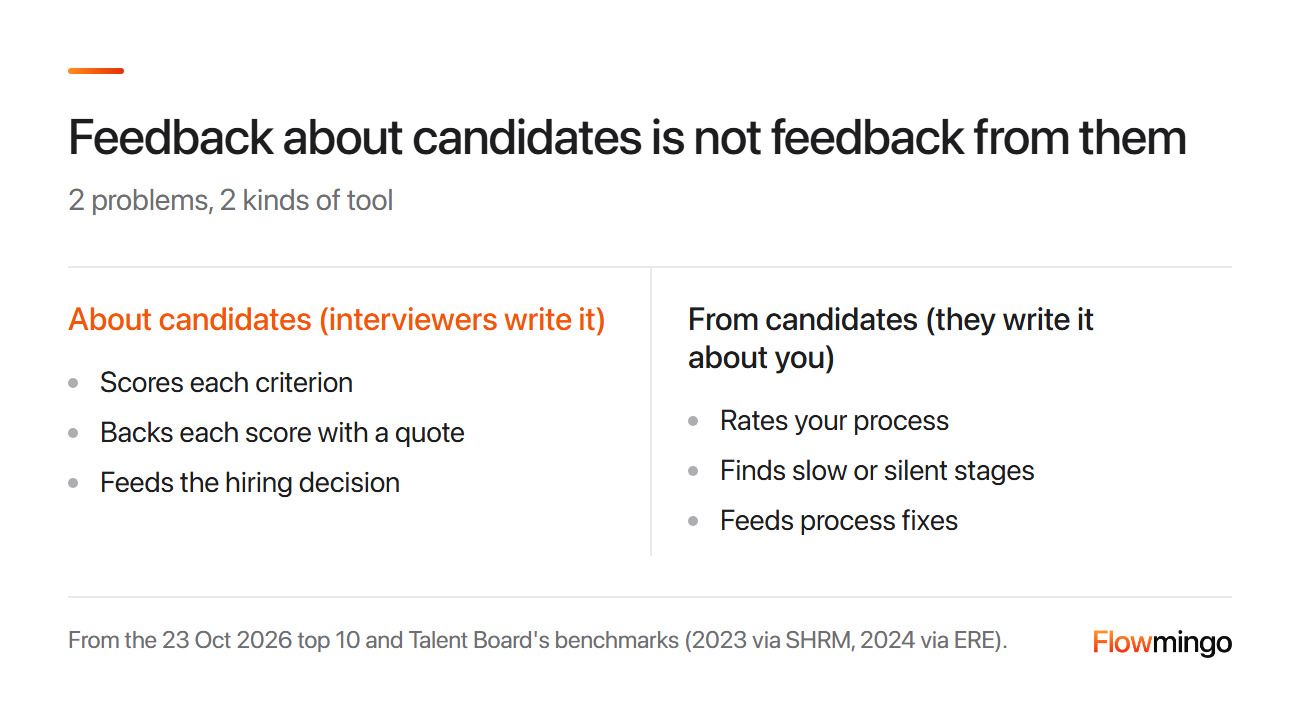
Feedback comparison: feedback about candidates scores each criterion, backs each score with a quote and feeds the hiring decision. Feedback from candidates rates your process, finds slow or silent stages and feeds process fixes.
The 2 meet in 1 place. Find the stage where candidates wait longest, then check your candidate interview feedback tool for late scorecards there. Add this question to your survey:
- "How long did you wait to hear back after your interview?"
If the answer is over a week, the fix is probably your 24-hour scorecard deadline, not the survey.
9. Our debriefs are won by the loudest voice. Should scores come in before the meeting?
Yes. Have every interviewer submit scores and quotes before the meeting, then discuss 1 criterion at a time, starting with the evidence only 1 person heard.
1 team says decisions go to "whoever talked the loudest in the room" (r/recruiting).
Talking first fails because groups discuss what everyone already knows. In Lu, Yuan and McLeod's foundational 2012 meta-analysis of 65 lab studies and 3,189 groups, shared facts got far more airtime.
When key facts were split, each member holding a piece, groups were 8 times less likely to find the right answer than groups seeing everything. These were lab groups solving set problems, not hiring panels.
In a debrief, the fact only 1 interviewer heard gets lost. In Stasser and Titus's foundational 1985 caucus simulation, discussion tended to keep distorted views, not correct them.
So start from section 3's weighted average, agreed before the interviews, and discuss only where scores split.
The method follows Kahneman, Lovallo and Sibony's Mediating Assessments Protocol, a foundational 2019 idea also in Noise. People judge each assessment alone before they discuss it.
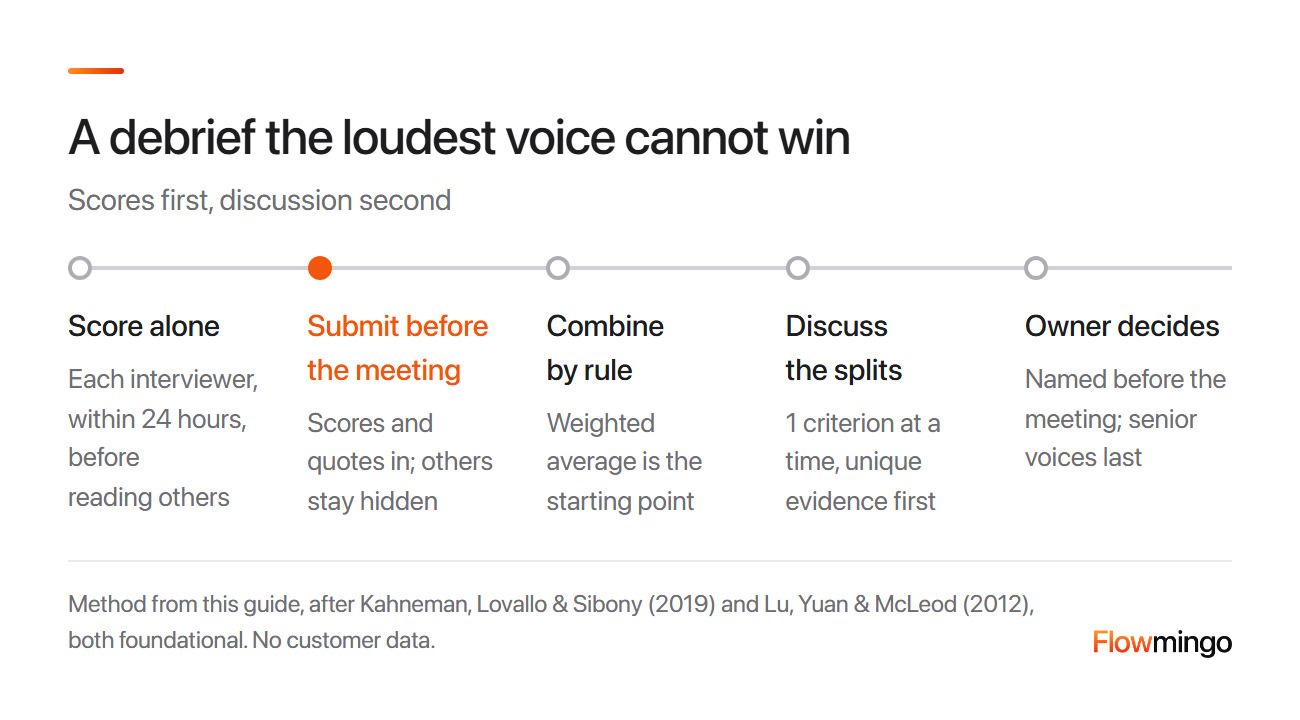
Debrief flow: score alone, submit before the meeting while others stay hidden, and combine by rule. Then discuss the splits 1 criterion at a time, and the owner decides.
Unique evidence goes first, and the owner is named before the meeting, with senior voices last.
Our guide to interview bias covers the other traps.
10. What should a candidate interview feedback tool include before I pick one?
Test 9 things in a 1-week trial before you buy. Each row says what to look for, why, and how to test it:
| Look for | Why | Test it in 1 week |
|---|---|---|
| A score per criterion, not 1 overall rating | Rule-based combining beat holistic judgement (Kuncel, section 3) | Score 2 past candidates in it |
| Evidence attached to each score | Free-form interviews weakened grade predictions (.31 vs .61, Dana, foundational) | Find the words behind any score |
| A post-interview prompt and a missing-scorecard list | 1 team went from 3 days to 2 minutes (section 1), and 1 Greenhouse user went looking for this report (r/recruiting) | Run 1 loop and see who gets chased |
| Other scores hidden until you submit | Groups miss facts split among members (Lu, section 9) | Submit as 2 test interviewers |
| Weights you can see | The overall should be checkable | Recompute 1 overall by hand |
| Export or API to your ATS | Notes in a side tool get ignored | Push 1 report into your ATS |
| Consent, retention and deletion | Illinois requires deletion within 30 days, and the ICO found data kept indefinitely | Ask how deletion works |
| An independent audit for bias, and a person deciding | NYC Local Law 144, the EU AI Act and Mobley v. Workday | Ask for the audit summary |
| Price at your volume, and a free tier | The FAQs at TalentEconomy, Easy-Peasy and Metaview all answer whether it is free | Price 12 months at your interview count |
Price at your volume, because a per-seat fee grows with every interviewer.
None of this is legal advice. NYC Local Law 144, enforced since July 2023 and foundational, covers NYC roles when a tool substantially assists or replaces the hiring decision.
It then requires an independent audit for bias within 1 year before use, a public audit summary, and candidate notice 10 business days ahead.
Illinois's AI Video Interview Act requires consent before AI analyses a video interview, and deletion within 30 days of a request. The EU AI Act lists AI that evaluates candidates as high-risk.
It is due to apply from 2 December 2027 (previously 2 August 2026). The date comes from Regulation (EU) 2026/1744, the Digital Omnibus on AI, in force since 27 July 2026.
In Mobley v. Workday, a US court let an alleged age-bias claim proceed as a nationwide collective action (Holland & Knight).
If your next step is the CV pile, see candidate shortlisting.
How Flowmingo helps
Flowmingo is a free AI hiring platform, and its AI interview, which applicants take in their own time, writes the first-round feedback for you.
Paid plans add video storage, branding and downloads, not more screening.
There is no native Greenhouse, Lever or Workday sync today, but a REST API, webhooks and MCP are free on every plan. Your team makes every decision. Try it as your candidate interview feedback tool for the first round on Flowmingo.
11. Sources
Every study, law and vendor page in this guide is listed below; community quotes link to their threads in the text. Flowmingo figures come from Flowmingo's own platform data.
- Dana, J., Dawes, R., & Peterson, N. (2013). Belief in the unstructured interview: The persistence of an illusion. Judgment and Decision Making, 8(5), 512-520.
- Easy-Peasy.AI. (n.d.). Interview feedback generator. Retrieved October 23, 2026.
- EU Artificial Intelligence Act. (n.d.). Annex III: High-risk AI systems referred to in Article 6(2). Retrieved October 23, 2026.
- European Parliament and Council. (2026). Regulation (EU) 2026/1744, the Digital Omnibus on AI. Official Journal of the European Union.
- Greenhouse. (2024, December 10). Greenhouse 2024 state of job hunting report. Greenhouse.
- Hawksford. (n.d.). Singapore Workplace Fairness Act: A guide for multinationals. Retrieved October 23, 2026.
- HireVue. (n.d.). AI interviewer. Retrieved October 23, 2026.
- Holistic AI. (n.d.). Illinois Artificial Intelligence Video Interview Act. Retrieved October 23, 2026.
- Holland & Knight. (2025, May 27). Federal court allows collective action lawsuit over alleged AI hiring bias. Holland & Knight LLP.
- Information Commissioner's Office. (2024, November 6). ICO intervention into AI recruitment tools leads to better data protection for job seekers. ICO.
- Kahneman, D., Lovallo, D., & Sibony, O. (2019, March 4). A structured approach to strategic decisions. MIT Sloan Management Review.
- Kahneman, D., Sibony, O., & Sunstein, C. R. (2021). Noise: A flaw in human judgment. Little, Brown Spark.
- Kuncel, N. R., Klieger, D. M., Connelly, B. S., & Ones, D. S. (2013). Mechanical versus clinical data combination in selection and admissions decisions: A meta-analysis. Journal of Applied Psychology, 98(6), 1060-1072.
- Lu, L., Yuan, Y. C., & McLeod, P. L. (2012). Twenty-five years of hidden profiles in group decision making: A meta-analysis. Personality and Social Psychology Review, 16(1), 54-75.
- Maurer, R. (2024, April 9). Candidate experience: Talent Board research (CandE). SHRM.
- Metaview. (n.d.). 7 top interview quality tools for better hiring decisions. Retrieved October 23, 2026.
- Middendorf, C. H., & Macan, T. H. (2002). Note-taking in the employment interview: Effects on recall and judgments. Journal of Applied Psychology, 87(2), 293-303.
- Ministry of Manpower, Singapore. (2025, January 8). Passing of Workplace Fairness Bill marks next step in building fair and harmonious workplaces. MOM.
- New York City Department of Consumer and Worker Protection. (n.d.). Automated employment decision tools (AEDT). Retrieved October 23, 2026.
- Pew Research Center. (2023, April 20). AI in hiring and evaluating workers: What Americans think. Pew Research Center.
- Polly. (n.d.). Interview feedback template. Retrieved October 23, 2026.
- Rubin, J. M., & Grissom, J. A. (2026). Leveraging large language models to assess short text responses (EdWorkingPaper No. 26-1385). Annenberg Institute at Brown University.
- Sackett, P. R., Zhang, C., Berry, C. M., & Lievens, F. (2022). Revisiting meta-analytic estimates of validity in personnel selection: Addressing systematic overcorrection for restriction of range. Journal of Applied Psychology, 107(11), 2040-2068.
- SIOP. (n.d.). Is cognitive ability the best predictor of job performance? New research says it's time to think again. The Industrial-Organizational Psychologist.
- Stasser, G., & Titus, W. (1985). Pooling of unshared information in group decision making: Biased information sampling during discussion. Journal of Personality and Social Psychology, 48(6), 1467-1478.
- Survale. (n.d.). Candidate experience surveys. Retrieved October 23, 2026.
- Talent Board & ERE Media. (2024, December). What sets CandE award winners apart: 2024 CandE benchmark research. ERE Media.
- TalentEconomy.ai. (n.d.). Interview feedback generator. Retrieved October 23, 2026.
- Typeform. (n.d.). Candidate feedback. Retrieved October 23, 2026.
- Flowmingo. (n.d.). How we score. Retrieved October 23, 2026.
- Flowmingo. (n.d.). FAQ. Retrieved October 23, 2026.
- Flowmingo. (n.d.). Pricing. Retrieved October 23, 2026.